
SEO
Crawl budget explained: what it is and who needs to manage it
Published by Zubair Afzal, responsible editor
First published Updated 6 min read
Start here
Is crawl budget your problem? Usually not
Most sites asking about crawl budget don’t have a crawling shortage. They have too many addresses, made faster than anyone planned. The fix is to stop making them.
Crawl budget is easy to sell: it sounds scarce and technical, and comes with long lists of fixes. Google’s own documentation is far calmer.
Definition
What is crawl budget? Capacity plus demand
Crawl budget is two things added together.
Crawl capacity limit: what your servers can handle, counted as connections at once and how long each stays open.
Crawl demand: how much Google wants to crawl. The documentation says it depends on your site’s size, how often it updates, page quality, and relevance against other sites. You don’t set it directly.
A faster, more reliable server raises the capacity limit, but nothing on your server raises demand; that comes from pages worth coming back for. Treat crawl budget as only a hosting issue and you may fix the half that wasn’t holding you back.
Google’s thresholds
Which sites need to manage crawl budget?
Google names the sites its crawl budget guidance is for. These are its numbers.
- Unique pages, with content changing about weekly: the large-site profile
- 1,000,000+
- Source: Google Crawling Infrastructure: crawl budget management for large sites
- Unique pages, with content changing very quickly: the medium-site profile
- 10,000+
- Source: Google Crawling Infrastructure: crawl budget management for large sites
- The “not modified” response, which Google names as saving crawl capacity
- 304
- Source: Google Crawling Infrastructure: crawl budget management for large sites
A third profile has no number. It’s sites where Search Console lists a large share of addresses as discovered but not indexed. That can include much smaller sites whose filters, parameters or internal search have made far more addresses than real pages.
How it adds up
The two parts of crawl budget
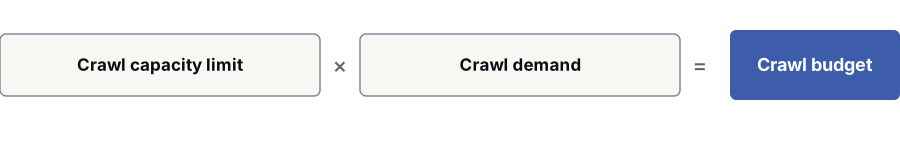
- Crawl capacity limit
- What your server can handle: connections at once and how long each stays open. A fast, reliable server raises it.
- Crawl demand
- How much Google wants to crawl, based on size, update frequency, page quality and relevance against other sites.
The test
Is crawl budget holding your site back? Five checks
If none of these flags a problem, the cause is elsewhere and crawl budget fixes won’t help.
- Count every address your site can create, including every filter, sort and parameter, and compare that with the pages you publish on purpose. A big gap is the finding that matters.
- Check your server logs for the share of crawler requests spent on addresses you don’t want indexed. If most go to parameters, you’ve made your own crawl problem.
- Check how long a new page takes to be requested for the first time. Days is normal on a large site. Weeks, on a section you update daily, is a warning sign.
- See if server response times rise when crawling is heaviest. If they do, you’re hitting the capacity limit.
- Read why pages are excluded from the index, not just the totals. “Discovered, not crawled” points to crawling; “Crawled, not indexed” points to page value. Each needs the opposite fix.
Sorting the advice
Crawl budget advice: what works and what doesn’t
| Dimension | What it does | What people often assume |
|---|---|---|
| Adding noindex to low-value pages | Keeps them out of search. Google still crawls the page to read the tag. | Frees crawling for other pages. Google says it still requests the page, so time is still used. |
| Blocking a section in robots.txt | Stops the request completely. It also makes any tag on those pages unreadable. | Sends crawling to better pages. Google is cautious about this unless you’re at the capacity limit. |
| Merging duplicate content | Google names this as helpful. Fewer near-identical addresses means less waste. | Tidying up with no real effect. |
| Returning 404 or 410 for removed pages | Google names this as helpful. It tells the crawler to stop coming back. | Something to avoid, because errors look bad in reports. |
| Keeping sitemaps current with change dates | Google names this as helpful, as long as the dates are accurate. | A way to force Google to crawl anything you list. |
| Making pages load faster | Google names this as helpful. Faster responses let Google fetch more in the same time. | Only a visitor experience or ranking issue. |
| Supporting “not modified” responses | Google names this as helpful. A 304 avoids resending a page that hasn’t changed. | A minor caching detail with nothing to do with crawling. |
| Removing pages from the sitemap | Removes a hint. Google can still find the addresses through links and will still request them. | Stops Google crawling them. It doesn’t. |
Questions
Crawl budget: common questions
Does my site have a crawl budget problem?
Probably not. Google’s guidance names three types of site it applies to.
1. Large sites with a million or more unique pages whose content changes about weekly.
2. Medium or larger sites with ten thousand or more pages whose content changes daily.
3. Sites where a large share of addresses shows as “Discovered – currently not indexed”.
If you’re none of those, the guidance says crawl budget isn’t your concern. A tool flagging a crawl budget issue usually just found lots of addresses.
Does adding noindex free up crawl budget?
No. Google advises against using noindex for this: it still requests the page, then drops it when it sees the tag.
Only a robots.txt disallow stops the request. Even then, Google says it won’t move the freed crawling to other pages unless you’re already at your crawl capacity limit, and advises against using robots.txt to shift budget around temporarily.
What improves crawling?
Google lists five: merge duplicate content, return proper status codes for removed pages, keep sitemaps updated with accurate change dates, make pages load faster, and support “not modified” responses.
All five cut wasted requests or make each one cheaper.
What does “Discovered – currently not indexed” mean?
It means Google knows the address exists but hasn’t fetched it, or chose not to store it. Google names a large share of addresses in this state as one sign crawl budget is worth checking.
On its own, it doesn’t prove a crawling shortage. It’s just as often about page value: if your site has made lots of thin, near-identical pages, the fix is fewer pages.
How do we measure this properly?
Use your server logs. They record what crawlers requested, when, how often, the status code and how long the response took.
Ask four questions. What share of requests hit pages you care about? How much went to parameters and filters? Do response times rise when crawling is heavy? How long before a new page is first requested?
Should we block our filtered URLs in robots.txt?
Sometimes, but decide it on purpose. Google publishes guidance on faceted navigation; the right approach depends on whether any filter combinations are worth indexing.
Google can’t read a blocked address, so any canonical or noindex tag on it becomes invisible. Blocking a section that’s already indexed is a slow, messy way to remove it, so plan the order of steps.
References
Sources for crawl budget
The official documents and research this page is based on. Platform rules change, so check the source before you act on a detail.
- Google Crawling Infrastructure: crawl budget management for large sites
- Google Search Central: in-depth guide to how Google Search works
- Google Search Central: robots.txt introduction
- Google Search Central: block search indexing with noindex
- Google Crawling Infrastructure: managing crawling of faceted navigation URLs
- Google Search Central: managing large sitemaps and sitemap index files
Start here
Told you’ve got a crawl budget problem?
Ask how it was measured. If the answer is a crawler tool’s count, not server logs and coverage data, get a second opinion before anyone blocks part of your site.
Rather check it yourself? Try our free SEO tools