
AI search
How to measure AI search visibility with a simple prompt panel
Published by Zubair Afzal, responsible editor
First published Updated 6 min readWe check this page every three months. Next check: .
The problem
Why AI visibility is a rate, and not a ranking
To measure AI search visibility, first accept that there’s no fixed position to track. A search results page is stable enough for a position to mean something. An AI answer is written fresh each time: ask the same question twice and the wording, the businesses named and the sources cited can all change. Personalisation, location and settings add more variation.
So the useful question is: across answers to these questions, how often are we named, and how often are we cited? That’s a proportion, estimated from samples, with a margin of error.
Google’s documentation says traffic from AI Overviews and AI Mode is counted in Search Console’s Performance report under the Web search type, but not shown on its own. Most other assistants give site owners no report at all. A prompt panel fills that gap.
Three metrics
Mention, citation and accuracy measure different things
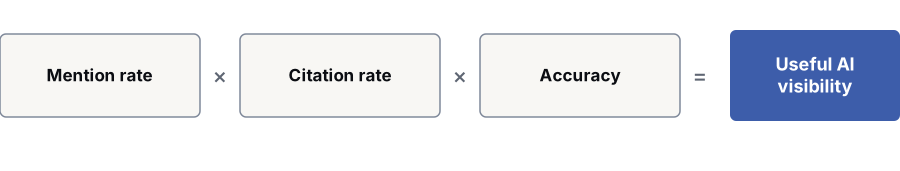
- Mention rate
- Share of answers that name the business at all.
- Citation rate
- Share that link to or credit a page on your own site.
- Accuracy
- Share of mentions that describe you correctly: services, prices, places.
The method
How to build and run a prompt panel
Write every step down, so next month’s number can be compared with this month’s.
Write the panel from real buyer questions
Use the questions customers ask your sales team, the searches in Search Console and the comparisons buyers make. Cover each stage: problem questions, category questions (“best X in Y”), comparisons and brand questions. Leave your name out of the questions unless you’re measuring brand accuracy.
You get: A numbered prompt list, grouped by stage
Fix the conditions
Decide which assistants, which mode (with or without web search), which location and language, and whether you’re logged in. Write them down. If the conditions change, you have a new starting point, not a trend.
You get: A one-page run specification
Run each prompt more than once
Answers vary, so one run is just an anecdote. Repeat each prompt several times per period, in fresh sessions. Save every answer in full, not a summary.
You get: A log of raw answers with dates
Score each answer the same way
For each answer, record: named or not, cited or not (and which URL), described correctly or not, and which competitors appear. Write the scoring rules before you start. Keep a sample of answers for a colleague to score again, as a check.
You get: A scored table, one row per answer
Report rates with their margin of error
Show mention rate, citation rate and accuracy for each stage and each assistant. Give the number of answers behind each rate and an approximate margin of error. Treat any change smaller than the margin as noise.
You get: A dated report you can compare period to period
Keep the panel stable, and version it
Add questions when the business changes. Keep a core set the same every period, so the trend means something. Record every change to the panel with its date.
The spreadsheet
Columns for your scoring sheet
A spreadsheet is enough to start: one row per answer, with these columns, gives you every rate with a simple count.
- Date, assistant, mode (web search on or off), location and whether you were logged in
- Prompt number and buyer stage, taken from your versioned prompt list
- Run number, so repeated runs of the same prompt stay separate
- Named: yes or no. Cited: yes or no, and the URL cited
- Accurate: yes, no or partly, with a note on what was wrong
- Competitors named in the same answer
- The full answer text, pasted in, so anyone can re-score it later
The arithmetic
How much a rate can move by chance
Worked arithmetic, not observed data. It shows the approximate 95% margin of error for a measured rate of 50%, using the normal approximation for a proportion from the NIST handbook: 1.96 × √(p × (1 − p) ÷ n).
| Dimension | Scored answers | Approximate margin of error | What it means |
|---|---|---|---|
| One question, 10 runs | 10 | About ±31 points | Too wide to read a trend from one question. |
| One question, 40 runs | 40 | About ±15 points | Useful for large changes only. |
| A stage of 20 questions, 5 runs each | 100 | About ±10 points | A sensible minimum for a monthly report. |
| Full panel, 400 answers | 400 | About ±5 points | Small changes start to be readable. |
Limits
What no method or tool can fix
Put these next to the numbers in every report, so nobody makes a decision the measurement can’t support.
- Your panel isn’t everyone’s questions. Real users ask things you didn’t think to include
- Real users are personalised, located and logged in differently from your test runs
- Assistants change models and sources without notice, which can move every number at once
- Test answers aren’t answers to real users, so rates aren’t a traffic forecast
- Repeated runs in one session aren’t independent, so use fresh sessions
- Being named isn’t the same as being recommended. Read what the answer says about you
Using the numbers
What to do with the results
Start with accuracy. If assistants get your services, prices or locations wrong, fix the sources they draw on first: your own pages, your Business Profile, and the directories and comparison pages that describe you. Then work on being mentioned more often.
Next, look at the stages where competitors are named and you aren’t. Those gaps usually point to missing content or pages that don’t answer the question. Published research suggests content changes can shift how often a source appears in AI answers. The GEO paper by Aggarwal and colleagues is one widely cited study, though its test conditions aren’t your market.
BOOSTD’s plans run this kind of sampled check on a schedule, and every plan includes it. Whether you use a tool or a spreadsheet, hold it to the method above.
Questions
Common questions about measuring AI visibility
Can AI search visibility be measured?
Yes, as an estimate. You can measure how often a set of questions gets an answer that mentions or cites you, across repeated runs. You can’t measure it like a rank tracker measures a position, because the answer changes between runs, users and days.
Does Google Search Console show AI Overviews traffic?
Only as part of the total. Google’s documentation says clicks and impressions from AI features, including AI Overviews and AI Mode, are counted in the Performance report under the Web search type. They aren’t reported separately, so Search Console shows the combined total and not the AI share.
How many prompts do I need?
Enough to cover the questions your buyers ask at each stage. For a business with one main service, that’s often a few dozen. You also need enough runs of each to make the rate meaningful. The margin of error shrinks with the square root of the number of runs, so four times the runs halves it.
How often should I measure?
Monthly suits most businesses. Weekly helps during a launch or after a big change. Checking more often is only worth it if each check has enough runs to read on its own.
How do I judge a vendor’s AI visibility score?
Ask how it was made. You want the prompt list, the assistants and settings used, the number of runs per prompt, the date range, and how mention, citation and accuracy are each counted. Without those, you can’t compare the score from one month to the next.
References
Sources for how to measure AI search visibility
The official documents and research this page is based on. Platform rules change, so check the source before you act on a detail.
Related
Keep reading on how to measure AI search visibility
- ongoing AI visibility tracking, run for youThe same method as a monthly service.
- how assistants choose sources
- what AI Overviews do to clicks
- AEO, GEO and SEO compared
- ChatGPT and Google search compared
- AI share of voice, defined
- what counts as a citation in an AI answer
- plans that include AI visibility checksEvery plan includes them; plans differ by size.
- how the platform runs the checks
Start here
Want a baseline you can compare month to month?
We write a prompt panel for your market, run it across several assistants on a fixed schedule, and show the number of answers behind every rate.
Rather check it yourself? Try our free SEO tools